What Happened
A service visit can be scheduled perfectly and still fail if the right part is not ready.
Field teams know this problem well. A technician arrives, diagnoses the issue, confirms that
a part is missing or wrong, and the customer has to wait for another visit. The visible
problem is a parts delay. The underlying problem is often readiness information scattered
across work orders, asset history, inventory, procurement, supplier lead times, and
technician notes.
Maintenance parts readiness is a practical automation opportunity because it sits at the
intersection of customer experience and operational cost. Every repeat visit consumes
scheduling capacity, travel time, customer patience, and administrative follow-up. When the
business can predict parts needs earlier and confirm readiness before dispatch, service
becomes more reliable.
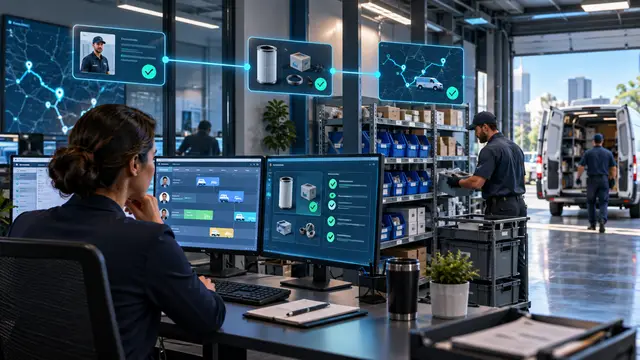
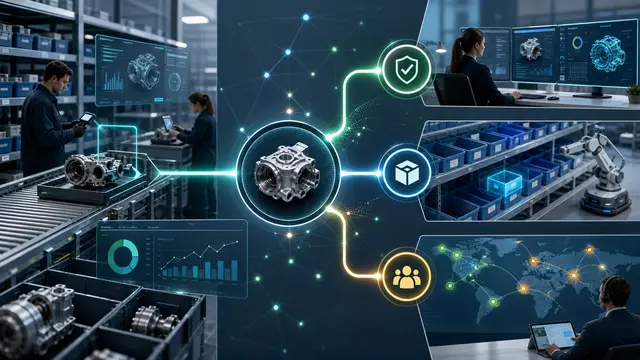
An AI maintenance parts readiness workflow reviews upcoming service work, installed asset
records, symptom descriptions, prior repairs, common failure patterns, inventory
availability, substitute part rules, supplier lead times, and location constraints. It then
identifies visits at risk of stalling because parts are missing, uncertain, incompatible,
delayed, or not reserved.
The workflow should not pretend to know more than experienced technicians. Instead, it
should gather signals that are hard to check manually at scale and present a readiness
decision. Ready to dispatch, needs parts reservation, needs technician review, needs
customer reschedule, or needs procurement action.
Why It Matters for Businesses
Service organizations often measure schedule adherence and response time, but those metrics
can hide parts readiness problems. A visit may happen on time while still failing to resolve
the issue. Customers care about resolution, not only arrival. When parts are not ready, the
business pays twice: once for the failed visit and again for the follow-up.
The issue becomes more difficult as product lines, asset ages, customer locations, and
supplier conditions vary. Experienced coordinators may know which calls deserve extra
checking, but that knowledge can live in memory or informal notes. New dispatchers may not
recognize part risk until after a visit stalls. Inventory teams may not see demand early
enough to reserve stock.
AI can improve the process by interpreting unstructured service notes and matching them with
structured asset and parts data. It can recognize that a symptom resembles prior repairs,
that an asset model has a known component pattern, that a substitute part requires an
adapter, or that a location has a longer replenishment path. These signals help teams act
before dispatch rather than after customer frustration.
The measurable benefits include fewer repeat visits, higher first-time fix rates, better
technician utilization, lower expedite costs, improved customer satisfaction, and stronger
inventory planning. The value is not only in prediction. It is in routing the prediction to
an action the business can complete before the service window.
The Practical Automation Opportunity
Start with a narrow service category where parts risk is common and data is available.
Examples include equipment repair, warranty service, facility maintenance, installation
follow-ups, or recurring asset inspections. Pick a category where repeat visits are costly
enough to justify a readiness control.
Define the readiness signals. Useful inputs include asset model, installation date, service
history, failure symptoms, work order type, technician notes, recommended parts lists,
inventory on hand, reserved stock, supplier lead time, customer location, and substitute
rules. The workflow should also know when data is missing, because uncertainty itself is a
readiness risk.
The AI review can generate a parts confidence level and a reason. For example, it may flag
that the likely replacement component is not reserved, that the asset has two possible
versions with different parts, or that the closest warehouse has stock but the scheduled
technician does not. That explanation helps coordinators solve the problem quickly.
Automation should then create the next step. Reserve the part, create a procurement task,
request a technician review, attach a suggested parts list to the work order, or recommend
rescheduling before the customer waits through an unproductive appointment. The system
should document the action taken so later analysis can improve the model.
Track outcomes carefully. Compare predicted risk with actual first-time fix results, parts
used, repeat visits, and customer reschedules. Review false positives with technicians so
the workflow becomes more useful rather than more noisy. The best systems learn from
completed work orders, not just from static part catalogs.
- Define the decision the workflow should make before selecting technology.
- Connect only the evidence sources that materially change that decision.
- Require reason codes so teams can understand and improve the automation.
- Measure avoided rework, faster cycle time, risk reduction, and recovered value.
Business Takeaway
Maintenance parts readiness is a practical place to apply AI because the cost of being wrong
is concrete. A missing part creates repeat work, unhappy customers, and wasted capacity. AI
can help by checking the signals before dispatch and turning uncertainty into a clear
operational action.
The starting point is simple: choose one service category, define the readiness signals,
route exceptions, and measure first-time fix improvement. That creates a focused workflow
that helps service teams keep promises instead of explaining preventable delays.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.
A useful implementation detail is to keep a short weekly review of the exceptions the workflow created. The review should ask which alerts protected a customer promise, which alerts were noise, which source system needs cleanup, and which owner was missing from the process. That operating habit prevents the automation from becoming another queue that people distrust.