What Happened
Support macros are supposed to make customer service faster, more consistent, and easier to coach. They give agents approved language for common questions, refunds, warranty steps, troubleshooting, billing explanations, appointment changes, and account updates. The problem is that macros often keep working after the business around them has changed. A price policy moves, a product is retired, a fulfillment promise changes, a compliance note is updated, or a workaround becomes obsolete, but the old response stays one click away from the customer.
That is how bad answers leak into otherwise good support operations. A customer asks why an invoice changed, and the agent uses a billing macro written before the new fee structure. A subscriber asks about cancellation timing, and the reply quotes the old notice period. A field service customer reports a failed part, and the macro sends them down a troubleshooting path that no longer matches the equipment. Each individual reply may look small, but the pattern can create escalations, refunds, rework, and trust problems.
The practical issue is not that agents are careless. Most agents are trying to move quickly through a queue while keeping tone, policy, and accuracy aligned. A busy support team may have hundreds of saved replies spread across a help desk, chatbot platform, shared inbox, CRM, customer portal, and team notes. Some are owned by a knowledge manager. Others were created by a team lead during a peak season and never formally retired. A few may be copied into personal snippets because they seemed useful at the time.
A support macro drift scorecard uses AI and automation to find the macros most likely to be wrong, risky, confusing, or misused before customers escalate. It does not replace the service leader, quality analyst, or product expert. It gives them a better review queue. Instead of asking someone to read every macro every quarter, the workflow compares saved replies against current policies, ticket outcomes, customer sentiment, escalation patterns, product changes, and agent edits.
The scorecard turns macro maintenance from a memory-based cleanup task into an operating rhythm. Each macro receives a practical risk view that explains why it deserves attention. A macro might be flagged because agents frequently rewrite it before sending. Another might be flagged because tickets using it reopen at a high rate. Another might mention a policy name, feature, service level, or time estimate that changed last month. The result is not a vague content audit. It is a prioritized list of replies that may be creating customer friction.
For a business owner or operations leader, this is a concrete way to improve service quality without slowing the queue. It helps support teams preserve speed while reducing the risk of sending confident but outdated answers. It also creates a measurable connection between customer-facing language and business outcomes such as first-contact resolution, reopen rate, escalation volume, refunds, and agent coaching time.
Why It Matters for Businesses
Support macros sit close to the customer experience. They are often the words customers see when they are already frustrated, confused, blocked, or waiting for help. If those words are accurate and empathetic, the customer feels guided. If they are stale, incomplete, or mismatched to the issue, the customer may feel dismissed, even when the agent meant well.
Macro drift creates risk because it hides inside normal productivity. A service director may see average handle time improving and assume the saved replies are helping. A support manager may see consistent wording and assume quality is stable. A customer success leader may see fewer long agent notes and assume the process is cleaner. Those measures can all look healthy while the actual reply content is slowly losing alignment with the business.
The impact shows up in several places:
- Customers reopen tickets because the first answer did not match their real problem.
- Agents add manual caveats because the approved macro is almost right but not quite current.
- Supervisors spend coaching time on issues that began with unclear or outdated wording.
- Product and billing teams receive escalations that could have been prevented with a cleaner first response.
- Chatbots repeat the same weak answer at higher volume because the macro became automation input.
- Compliance or privacy language becomes inconsistent across channels.
The cost is not only customer dissatisfaction. It is operational drag. A wrong macro creates a second contact. A confusing macro creates a clarifying question. A policy mismatch creates a supervisor review. A poorly worded exception creates an account manager apology. A macro that promises something the company can no longer deliver may create a refund, credit, or goodwill concession.
Small and midsize businesses feel this sharply because support knowledge often lives with a few experienced people. One team lead knows which reply is safe for enterprise customers. One billing specialist knows which refund language has changed. One product manager knows which troubleshooting step was retired. When those details do not flow into the macro library, the business depends on informal correction. That works until ticket volume rises, the experienced person is unavailable, or a new agent follows the saved reply exactly.
The scorecard also matters because AI adoption increases the reach of old content. Many companies start using AI to draft replies, summarize conversations, or power customer-facing bots. Those systems often learn from existing macros, help articles, and ticket history. If the source material contains stale instructions, AI can scale the drift instead of fixing it. The safer path is to govern the building blocks first.
Support leaders do not need a giant transformation to begin. They need a way to answer practical questions:
- Which macros are most often edited before sending?
- Which macros appear in tickets that later reopen or escalate?
- Which macros mention policies, prices, product names, or service levels that recently changed?
- Which macros are used by only one person, one region, or one legacy queue?
- Which macros generate lower customer satisfaction than similar replies?
- Which macros are missing an owner, review date, or approved exception path?
These questions convert quality management from opinion into evidence. A supervisor no longer has to say, "I think this reply may be causing problems." They can show that the macro was used 180 times this month, edited by agents 70 percent of the time, tied to a higher reopen rate, and still refers to an old response window. That is a business case for action.
The Practical Automation Opportunity
A support macro drift scorecard starts with a clear inventory. The business should identify every place saved replies live, not just the official help desk library. That may include help desk macros, chatbot intents, CRM email templates, shared inbox snippets, customer portal responses, onboarding scripts, warranty language, refund templates, outage messages, and escalation notes. The first automation does not need every channel, but leaders should know the full map so hidden libraries do not undermine the work.
The next step is to connect each macro to evidence. AI is useful because it can compare text, detect similarity, classify intent, identify policy references, and summarize differences between versions. Automation is useful because it can collect the signals repeatedly and route the review to the right owner. Together, they create a living scorecard rather than a one-time cleanup spreadsheet.
A practical scorecard might evaluate five dimensions:
- Accuracy risk: Does the macro reference policies, pricing, product behavior, service windows, shipping rules, or legal language that may have changed?
- Usage risk: Is the macro used often, used suddenly more often, or used by agents who work in different queues than the original owner expected?
- Outcome risk: Are tickets using the macro more likely to reopen, escalate, receive low satisfaction scores, or require manager review?
- Edit risk: Do agents frequently rewrite, delete, or add caveats to the macro before sending it?
- Governance risk: Does the macro lack an owner, approval date, review date, source link, or retirement rule?
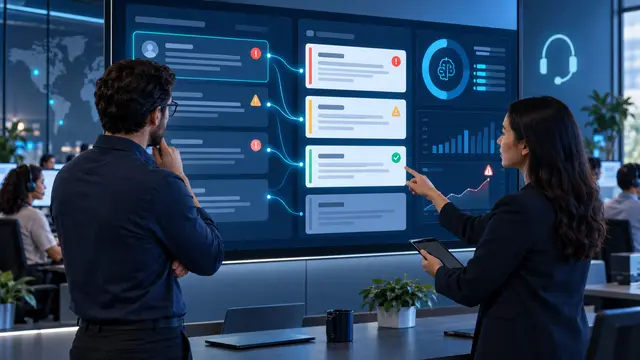
The score should be explainable. A macro should not simply receive a red, yellow, or green label with no context. The review card should tell the owner what triggered the flag, which tickets provide examples, what source record may conflict with the macro, and what decision is needed. A support operations manager should be able to open the card and know whether the next action is rewrite, retire, merge, restrict, approve, or investigate.
For example, imagine a software company with a saved reply for invoice questions. The macro says that payment method updates take effect within twenty-four hours. Billing changed that process to two business days after a fraud-control update. Agents know this and often edit the reply manually, but the macro still contains the old promise. The scorecard catches the mismatch by comparing the macro to the current billing policy, noticing frequent agent edits, and seeing reopened tickets tied to payment timing. The review card goes to the billing support owner with example tickets and a suggested rewrite for approval.
Now consider a field service company. A macro tells customers to reset a device before scheduling a technician. The product team retired that reset step for a newer model because it can erase diagnostic logs. Agents still use the macro because the issue looks familiar. The scorecard flags the reply because it mentions a retired troubleshooting step and appears in tickets that later require escalations. The service manager can split the macro by product model and add a safety note before more customers receive the wrong instruction.
The workflow should keep humans in control of customer-facing language. AI can prepare evidence and draft suggested changes, but final approval should stay with the person accountable for the policy, product, or customer promise. That keeps the system useful and reduces the risk of confident automation publishing a bad answer at scale.
A strong review process includes:
- A named owner for every high-use macro.
- A source-of-truth link for the policy, product note, or procedure behind the answer.
- A review trigger when related policies, release notes, pricing, or service windows change.
- A weekly queue for high-risk macros and a monthly review for lower-risk items.
- A disposition field such as approved, rewritten, retired, merged, restricted, or needs specialist review.
- A measurement loop that checks whether reopen rate, escalation rate, or edit rate improved after the change.
The first pilot can be simple. Choose one support queue with visible pain, such as billing questions, warranty claims, appointment changes, account access, or product troubleshooting. Pull the ten to twenty most-used macros. Compare them with recent ticket outcomes and agent edits. Ask a service lead and a policy owner to review the highest-risk five. Measure what changes after thirty days.
The most important design choice is focus. Do not turn the first version into a full knowledge management program. The narrow goal is to find saved replies that may be creating bad answers before customers escalate. If the scorecard helps the team remove or improve a few risky macros, it has already created value. From there, the same pattern can expand to chatbot responses, public help center articles, onboarding emails, and internal playbooks.
Business Takeaway
A support macro drift scorecard gives businesses a practical way to protect service quality while keeping response speed. It recognizes that saved replies are not static assets. They are operational controls that need ownership, evidence, and review. When a macro is wrong, the damage travels directly to the customer. When a macro is governed well, agents gain confidence, customers receive clearer answers, and managers spend less time cleaning up avoidable escalations.
The return comes from reducing preventable second contacts. Fewer reopened tickets mean agents can focus on new issues. Fewer escalations mean supervisors can spend more time coaching patterns instead of rescuing individual cases. Cleaner macros also help AI tools perform better because the source material is more reliable. That matters as more companies use AI to draft replies, summarize ticket history, recommend next actions, or operate self-service support.
This workflow is also a good fit for companies that want measurable automation without a sprawling project. The data already exists in most support environments: macro text, ticket categories, timestamps, edits, reopen events, escalation tags, customer ratings, and policy sources. The hard part is turning those signals into a review rhythm that people trust. AI can assemble the evidence, but leadership still defines what good customer communication means.
The best scorecards are modest at first. They do not claim to judge every support interaction. They identify which saved replies deserve human attention this week and why. That is enough to change behavior. A team that reviews five risky macros a week can steadily reduce drift, preserve institutional knowledge, and make service automation safer.
This week, pick one support queue, export the ten most-used macros, and ask three questions for each one: what source proves this answer is still true, how often do agents edit it before sending, and what happens to tickets after customers receive it?