What Happened
Website uptime incidents are often treated as technical events first and customer communication events second. Monitoring tools detect a slowdown, outage, failed checkout, broken form, expired certificate, or degraded integration. Engineers investigate the cause. Operations waits for updates. Customer service starts receiving questions. Sales may not know whether prospects are affected. Marketing may pause campaigns too late. By the time a message is drafted, the company has already lost valuable minutes.
The issue is not only downtime. It is coordination. A website incident can affect different audiences in different ways. A public homepage issue is different from a customer portal login problem. A broken lead form is different from a failed payment callback. A slow knowledge base is different from a regional outage. Each scenario requires a different response, owner, urgency, and follow-up. When teams rely on manual interpretation, they risk either over-communicating minor issues or under-communicating serious ones.
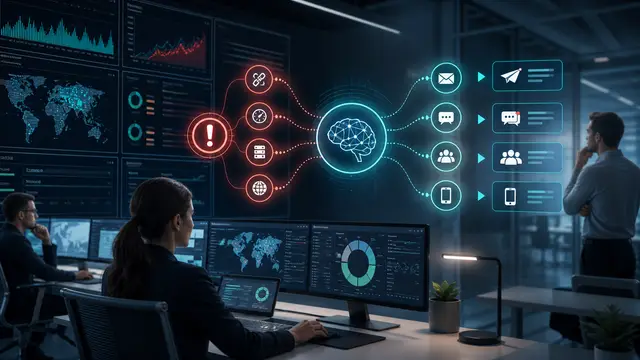
AI and automation can help translate uptime signals into communication actions. The system should not replace engineering diagnosis, and it should not invent facts. Instead, it can classify what is known, identify likely affected workflows, suggest the right internal audience, prepare approved message drafts, and trigger review tasks. The result is a faster bridge between technical monitoring and business communication.
This matters for companies that use their websites as sales engines, customer portals, support hubs, booking systems, ecommerce storefronts, or operational self-service tools. If customers depend on a digital workflow, uptime incidents need a communication process that is as disciplined as the technical response.
Why It Matters for Businesses
Poor incident communication creates compounding damage. Customers may forgive a temporary technical problem if the company acknowledges it clearly and provides realistic next steps. They are less forgiving when they have to discover the problem themselves, repeat the same support question, or receive conflicting answers from different teams. Internal confusion also increases cost. Support agents create duplicate tickets. Account managers send one-off explanations. Leaders ask for status updates while engineers are still investigating.
A practical communication workflow reduces that drag. It helps teams answer four questions quickly: What happened, who might be affected, what should we say now, and who needs to approve the message? Those questions do not require a complete root cause analysis. They require disciplined triage.
The business impact can be measured:
- Time from alert to internal incident classification.
- Time from confirmed customer impact to first approved message.
- Number of duplicate support tickets tied to the incident.
- Consistency of language across support, sales, and status channels.
- Percentage of incidents with a documented customer impact assessment.
- Completion of post-incident follow-up tasks.
AI is useful because monitoring alerts are technical and fragmented. One alert may show response time. Another may show form failures. Another may show integration errors. A human still needs to confirm the facts, but AI can assemble a first-pass summary and map signals to customer-facing workflows. It can help the business avoid staring at raw alerts while customers wait for clarity.
The Practical Automation Opportunity
A strong automation starts with incident categories. Define the website workflows that matter most: lead forms, checkout, customer login, booking, support portal, knowledge base, chat, payment, file upload, search, and integrations. For each workflow, define severity levels and communication rules. For example, a failed lead form during a paid campaign may require sales and marketing notification even if public uptime remains high. A customer portal login outage may require support scripts and account manager awareness.
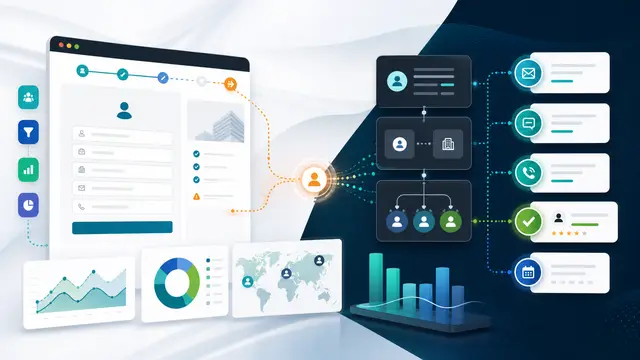
Next, connect monitoring tools to a triage queue. Inputs may include uptime alerts, synthetic test failures, error logs, form submission drops, analytics anomalies, support ticket spikes, and deployment events. The AI layer can summarize the signals, identify likely affected workflows, and compare the incident against predefined categories. It should clearly separate confirmed facts from possible implications. That distinction protects credibility.
For each incident, the workflow can generate:
- An internal summary for engineering, support, sales, and leadership.
- A customer impact hypothesis that requires owner confirmation.
- A recommended severity level.
- Draft support talking points using approved language.
- A draft status update when public communication is warranted.
- Tasks for post-incident customer follow-up.
- A record linking alerts, decisions, messages, and resolution time.
Approval rules are essential. The system can prepare messages, but a responsible owner should approve anything customer-facing. Legal or executive review may be required for severe outages, regulated industries, or commitments about credits and service levels. For lower-risk issues, a support lead may approve a short message from a preapproved template.
The automation should also support the recovery phase. Once the incident is resolved, it should prompt the owner to update internal teams, close support macros, notify affected accounts if promised, and log lessons learned. AI can help draft a post-incident summary from the timeline, but it should never make claims that engineering has not confirmed.
Start with one high-value workflow, such as lead forms or customer login. Build the category, data inputs, owner rules, and message templates. Run the workflow in internal-only mode for a few incidents. Once the classifications are reliable, allow approved external communication drafts.
The workflow should include scenario templates before an incident happens. Templates for form failure, login disruption, checkout delay, degraded page speed, regional access problem, expired certificate, and third-party integration failure give teams a starting point. AI can adapt the template to confirmed facts, but the base language should be approved in advance. That reduces review pressure when time is tight.
A second practical detail is missed-action recovery. If a lead form fails for two hours, the response is not complete when the form is fixed. The business may need to identify missed submissions, review analytics gaps, check ad spend during the outage, and ask sales to follow up with affected prospects. AI can create that recovery checklist from the incident category. That is where uptime triage connects directly to revenue protection.
Before scaling this workflow, document the baseline. Capture current cycle time, rework, escalation volume, missed commitments, and the decisions managers wish they had seen earlier. Then pilot the automation with a small group, review exceptions weekly, and tune the rules based on evidence. The strongest results usually come from a narrow workflow that teams trust, not a broad launch that produces more alerts than decisions.
Ownership should be explicit before the alert fires. Engineering may own diagnosis, but support may own customer language, marketing may own public web messaging, sales may own prospect follow-up, and leadership may own high-severity approval. The automation should create the right tasks automatically based on incident category. It should also show who has not responded when a decision is waiting. During an incident, unclear ownership wastes more time than imperfect tooling.
The system should integrate with the channels teams already use. That may include ticketing tools, incident management platforms, chat channels, CRM tasks, status page drafts, support macros, and email approval flows. A separate dashboard can be useful, but it should not be the only place work appears. The point is to move communication actions into the operating rhythm of each team.
Measure the workflow with after-action reviews. For each incident, compare alert time, classification time, first internal update, first approved customer-facing message, resolution update, and recovery task completion. Also review whether any message had to be corrected. Accuracy matters as much as speed. Over time, this creates a library of incident patterns and approved response language that makes the next event easier to manage.
Do not overlook internal communication. A short internal note can prevent dozens of side conversations. It should state the affected workflow, current status, customer impact if known, who owns the next update, what teams should say if asked, and when the next checkpoint will occur. AI can draft that note from the incident record, but the owner should approve the facts. This keeps support, sales, leadership, and technical teams aligned while engineering investigates.
A mature workflow can also connect incidents to prevention work. If the same type of form failure appears after deployments, the post-incident task should include release checklist changes. If slow pages appear during campaign traffic, marketing and web operations should review capacity planning before the next launch. If a third-party integration repeatedly causes customer disruption, vendor management may need to join the review. The communication workflow becomes more valuable when it sends recurring causes back into operational planning.
That prevention loop turns incident response from a reactive scramble into a measurable resilience habit.
Business Takeaway
Website incidents are business moments, not only technical tickets. AI-assisted triage helps teams convert monitoring noise into clear communication actions while preserving human approval and factual discipline.
The practical move is to define critical website workflows, classify incidents against those workflows, draft messages from confirmed facts, and route approvals quickly. Customers do not need perfect technical detail in the first minute. They need timely, accurate, coordinated communication.