What Happened
Every operations team has exception queues. Orders need review because an address is incomplete. Invoices stall because a purchase order does not match. Service tickets reopen because the first answer missed the real issue. Shipments require manual attention because inventory records disagree. Approvals pause because a field is blank, a rule is unclear, or a manager is out. The queue becomes part of daily life, and the team measures how quickly people clear it.
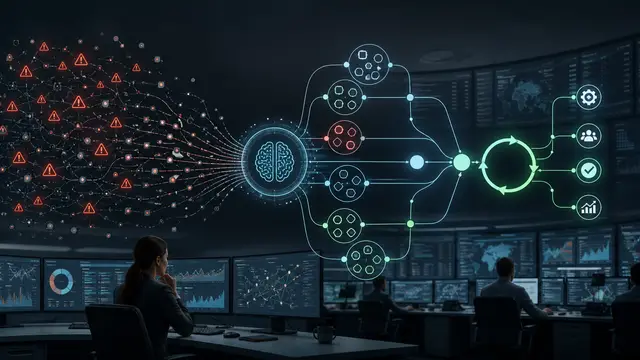
Clearing exceptions matters, but it is not the same as improving the process. If the same exception returns every week, the business is paying people to work around a design problem. The queue hides the root cause because each item looks urgent on its own. Managers see aging counts and service levels, but they may not see the pattern connecting the work. AI can help by grouping exception records, summarizing repeated causes, and pointing leaders toward fixes that reduce future volume.
This is a practical use for AI because exception records contain messy but valuable clues. Notes, status changes, reason codes, attachments, timestamps, customer messages, and manual corrections all tell a story. Traditional reporting can count categories, but it often misses the language that explains why work keeps failing. AI can read those details and identify recurring themes such as missing setup data, confusing form labels, unclear customer instructions, outdated product rules, handoff gaps, or approval thresholds that no longer match the business.
The goal is not to eliminate every exception. Some exceptions are legitimate controls. A high-value refund should require review. A contract deviation should route to legal. A suspicious payment change should pause. The opportunity is to separate healthy control exceptions from preventable rework. AI can help teams see which exceptions protect the business and which ones reveal a process that needs repair.
When operations leaders treat exceptions as improvement signals, the queue changes meaning. It becomes a source of process intelligence instead of an endless backlog.
Why It Matters for Businesses
Exception work is expensive because it consumes skilled attention without always creating new value. A person who spends three hours a day resolving preventable mismatches is not improving customer experience, analyzing trends, or strengthening controls. The business may hire more people to handle volume when the better answer is to remove the cause of the volume.
Customers feel the cost too. Exceptions create delays, duplicate requests, inconsistent answers, and avoidable escalations. A customer does not care that an internal field was missing or two systems disagreed. The customer experiences a late order, a delayed invoice correction, a repeated question, or a vague update. Over time, those small failures reduce confidence.
Exception queues also distort management attention. A dashboard may show that the team cleared ninety percent of exceptions within target. That sounds healthy until leaders realize the same root cause generated hundreds of unnecessary items. Speed can hide waste. AI-assisted pattern detection gives leaders a better view by asking not only "how fast did we clear it" but also "why did it appear again."
The business impact can be measured in several ways:
- Fewer repeated exceptions per transaction
- Shorter cycle times for orders, invoices, tickets, and approvals
- Lower rework hours
- Fewer customer follow-up contacts caused by internal delays
- Better first-pass accuracy in upstream processes
- More stable staffing needs during peak periods
- Stronger control evidence for exceptions that should remain
AI also helps cross-functional ownership. Many exceptions are solved downstream but caused upstream. Accounts payable fixes supplier invoice issues that purchasing created. Customer service handles order confusion created by product data. Sales operations cleans CRM errors created during lead capture. Warehouse teams resolve fulfillment issues caused by master data. When AI groups exceptions by likely source, leaders can assign improvement work to the right team.
This reduces blame because the conversation becomes evidence-based. Instead of saying "the queue is too big," managers can say "thirty-one percent of avoidable order exceptions this month involved missing delivery constraints from the website form, and the issue is concentrated in three product families." That statement leads to action.
The Practical Automation Opportunity
Start with one high-volume queue that has consistent records. Good candidates include invoice exceptions, order holds, service reopenings, shipping issues, approval delays, failed automation runs, customer data corrections, or CRM handoff errors. Choose a queue where reducing volume would create visible operational value.
Create a data set that includes the exception reason, source system, timestamps, owner, resolution action, notes, related customer or supplier messages, and final status. Add transaction attributes that may explain patterns, such as product, location, channel, customer segment, supplier, salesperson, region, or workflow version. AI needs context to find useful clusters.
Use AI to classify exceptions into three groups. The first group is valid control work, where review is intentional and should remain. The second group is temporary operational noise, such as a one-time supplier outage or unusual event. The third group is preventable rework, where a process, data field, instruction, integration, or training issue keeps producing avoidable items. The third group is where improvement value usually lives.
For each repeated pattern, the system should produce a root cause brief. A useful brief includes:
- Pattern summary in plain business language
- Example records with source links
- Estimated monthly volume and labor impact
- Customer or revenue impact
- Likely upstream owner
- Suggested process, data, automation, or training fix
- Confidence level and review notes
Do not let the workflow stop at insight. Assign each approved root cause to an owner, set a target date, and track whether the exception volume changes after the fix. This is where many analytics projects fail. They produce interesting charts, but no operating cadence. The AI output should feed a weekly improvement review where leaders decide which root causes deserve action.
Automation can also test whether a fix worked. If a website form is changed to capture delivery constraints, the exception queue should show fewer delivery clarification holds. If supplier setup instructions are rewritten, invoice mismatches should decline. If a CRM required field is added, sales handoff errors should drop. AI can compare before and after patterns and flag when exceptions return.
Governance matters. Teams should review AI-generated root cause labels before acting on them. AI can misread a note, overstate a pattern, or miss a policy reason. Keep the human decision visible. The system recommends likely causes and evidence. Leaders approve the improvement work.
The first pilot should avoid too many categories. Pick one queue, review the last sixty to ninety days, identify the top five preventable patterns, and fix two. That limited scope teaches the team how to evaluate AI findings without overwhelming them.
A strong program also distinguishes between apparent causes and confirmed causes. AI may notice that many order holds involve one product line, but the confirmed cause might be a missing configuration rule, a training issue in one branch, or a supplier data feed that changed format. The AI finding should open the investigation, not close it. Operations leaders should require evidence before assigning a permanent fix.
The improvement backlog should have economic discipline. Not every repeated exception deserves immediate redesign. A pattern that causes ten minutes of rework per month may be acceptable. A pattern that delays invoices, affects top customers, or consumes hours of senior analyst time deserves attention. AI can estimate impact, but managers should validate the assumptions using time studies, sampled records, or workflow timestamps.
Exception prevention also needs change management. If the fix is a new required field, teams need to understand why it matters. If the fix is a revised approval rule, managers need to trust the control. If the fix is an integration change, technical owners need monitoring after deployment. Treat each root cause fix as a small operating change with owner, test plan, release note, and post-change measurement.
The best reviews include frontline context. People who clear exceptions know which issues are truly wasteful and which ones protect the business. AI can summarize thousands of records, but it cannot replace the judgment of the people who understand customer behavior, supplier habits, and system quirks. Pair the AI cluster with a short frontline review, then decide whether to fix, monitor, or leave the exception in place as a control.
It is also worth keeping a small library of approved fixes. If a root cause is missing master data, the fix pattern may include field ownership, validation rules, and weekly completeness reporting. If the root cause is unclear instructions, the fix pattern may include revised templates and better examples. If the root cause is an integration timing problem, the fix pattern may include retry logic, monitoring, and reconciliation. Reusable fix patterns help teams move from diagnosis to action faster.
Business Takeaway
Exception queues should do more than absorb operational friction. They should teach the business where friction starts. AI can read the messy details inside exception records, group recurring issues, and turn repeated manual work into root cause fixes. The payoff is not only faster queue clearing. It is lower rework, fewer customer delays, better upstream design, and an operations culture that improves the process instead of normalizing the workaround.