What Happened
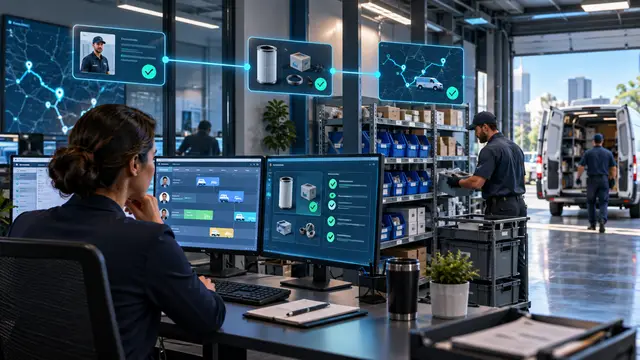
Field service dispatch is usually managed in the space between customer promises and finite capacity. A dispatcher must consider technician skills, geography, parts availability, contractual response windows, traffic, job duration, and unexpected emergency calls. When those inputs live in different systems, the daily schedule becomes a sequence of phone calls and manual adjustments. The team may work hard and still produce inconsistent arrival windows and avoidable travel time.
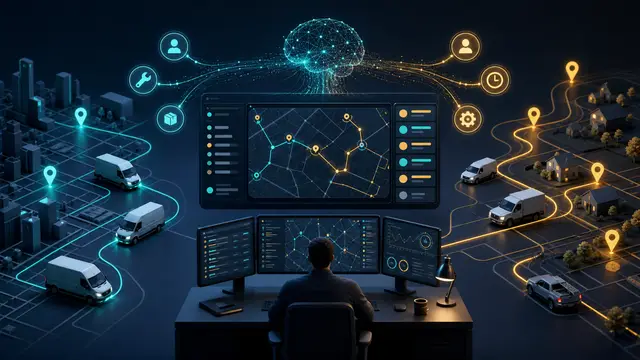
AI scheduling can turn that coordination problem into a living operational plan. It can combine work orders, technician qualifications, historical job duration, locations, parts status, and service commitments to recommend assignments and routes. When a new priority job appears, the workflow can show the tradeoffs rather than silently reshuffling the day. Dispatchers remain accountable for the decision, but they start with an explainable recommendation instead of a blank map.
The most useful systems do not promise a perfect schedule. They make uncertainty visible. A job with an unreliable duration estimate, a technician without a verified required credential, or a part that has not been confirmed should be flagged before it becomes a missed appointment. That changes dispatch from reactive recovery to early risk management.
Why It Matters for Businesses
Predictable dispatch improves both customer experience and operating margin. Narrower, more credible arrival windows reduce inbound status calls. Better skill matching reduces repeat visits. Less windshield time lets the same team complete more planned work without asking people to run a harder day. The effect can be measured in on-time arrival, first-time fix rate, travel hours per completed job, overtime, and reschedule rate.
Governance is essential because schedules affect employees and customers. A business should document which constraints are non-negotiable, such as safety certifications, union rules, break requirements, or contractual priority. The recommendation engine should never bypass those constraints. It should also present the reason for a suggested reassignment, so a dispatcher can recognize when local knowledge should override the system.
Historical data becomes valuable when it is treated as operational evidence. If certain job types routinely exceed estimates, that is not merely a scheduling nuisance. It may signal incomplete intake questions, a training gap, or a recurring parts problem. The scheduling workflow can surface these patterns for service leaders before they become chronic performance issues.
The Practical Automation Opportunity
Map the dispatch decision in plain language before selecting technology. List the work-order fields that determine a viable assignment, identify the systems that own them, and agree on a clear definition of a completed job. Clean skill and territory data first; sophisticated scheduling cannot compensate for a technician record that is out of date.
Use a morning planning workflow that produces recommendations with clear reasons and a dispatcher review. Then add event-driven replanning for cancellations, emergency calls, late parts, and technician absences. Notify customers only after a human or policy-approved decision has confirmed the revised commitment.
Run a pilot in one region or service line. Compare the recommended plan with the existing method for several weeks, record overrides and their reasons, and use that feedback to refine the constraints. Expand when the business can show not only fewer miles but better promise keeping.
Implementation should start with a decision inventory. List every decision the current team makes, the evidence it uses, the role that owns the final decision, and the downstream system affected. That exercise prevents a common automation mistake: encoding an informal shortcut as though it were policy. It also reveals where exceptions cluster. A rule that has ten different informal exceptions is usually not ready to be automated without a clearer business definition.
Data stewardship deserves explicit ownership. The workflow needs named owners for source fields, reference data, business rules, model prompts, and approval thresholds. When a field changes meaning or a source system is replaced, someone should assess the downstream effect before the automation quietly produces misleading work. A monthly operating review can examine data quality, overdue items, overrides, and feedback from the people using the queue.
Design the human handoff as carefully as the automated step. A reviewer should receive a concise brief, direct access to source evidence, a short set of allowed actions, and a clear escalation route. The reviewer should not need to reconstruct the case from multiple inboxes. At the same time, the system should not hide uncertainty. Low-confidence recommendations and missing evidence should be visible, because they are often the most valuable work for an experienced employee.
A phased rollout reduces risk. Begin with observation mode, where the workflow creates recommendations but does not change a record. Compare its output with experienced staff decisions and record the reason for every material difference. Next, allow policy-approved actions for high-confidence, low-risk cases while retaining review for exceptions. Only after stable results should the business expand the population, source systems, or decision scope.
Build a practical measurement baseline before launch. Capture current turnaround time, rework, backlog age, escalation volume, and the effort spent requesting missing information. After rollout, compare the same measures by work type, not just as one blended average. A faster process that creates more reversals, customer confusion, or control failures is not a successful process. The intended result is reliable capacity: less time spent finding and formatting information, and more time spent deciding and improving.
Communicate the operating model to the people affected by it. Explain what the workflow will do, what it will never do without approval, how to correct a recommendation, and where feedback goes. Adoption improves when employees see that automation removes repetitive gathering work while preserving their authority over business exceptions. It also produces better feedback, which is necessary to keep the workflow accurate as policies and customer behavior change.
Finally, keep the workflow reviewable. Maintain a record of source inputs, generated recommendations, user decisions, timestamps, and rule versions. Periodically sample completed cases, including cases that the system marked as routine. This audit habit supports governance and gives the business a way to find process improvement opportunities that would be invisible in a purely manual operation.
Consider integration failure as an operating condition, not an edge case. A source system may be unavailable, an attachment may arrive late, or a required identifier may be malformed. The workflow should show a clear status, preserve what was received, avoid duplicate actions on retry, and route the case to a recoverable exception path. A well-designed recovery path protects both customer experience and employee confidence.
Decision thresholds should be reviewed against the cost of being wrong. In some workflows, a false positive creates little harm and can be corrected easily. In others, a mistaken action can affect a customer, a ledger, a compliance obligation, or a security boundary. Match automation scope to that risk. Require stronger evidence and human approval where the impact is high, and use routine low-risk actions to build confidence gradually.
The workflow also needs a practical change-management cadence. Business policies, supplier practices, product offerings, and staffing patterns change. Set a recurring time to review whether the original assumptions still hold, whether new exceptions should become standard paths, and whether old rules can be retired. This keeps the automation aligned with actual operations rather than preserving a snapshot of how work used to happen.
At leadership level, report outcomes alongside limitations. Share where automation reduced cycle time or prevented rework, but also share the exceptions that remain manual and why. That transparency helps the business direct improvement investment to the right place. It reinforces the central principle: automation should make responsibility clearer, evidence easier to use, and service more dependable.
Before expanding the workflow, test its behavior with representative edge cases. Include incomplete records, contradictory source values, unusual amounts or dates, cases that cross ownership boundaries, and situations that require an exception approval. Ask the people who do the work to review the outcomes. Their experience will identify ambiguity that is invisible in a process diagram and will improve both the instructions and the data model.
Keep automation messages useful. A reminder should identify the item, the required next step, the deadline, and a direct route to act. An escalation should explain what has already been attempted and why the item needs attention. Avoid sending broad status messages that force recipients to search for context. Good notification design is a material part of operational productivity.
As the workflow matures, look for upstream prevention. Repeated exceptions are rarely only a queue-management problem. They may be caused by a confusing customer instruction, an incomplete form, a missing validation, or a policy that is difficult to apply. Use exception data to improve the originating process, then verify that the change actually reduces the recurring issue.
Document the benefit in business language. Employees, leaders, and customers should be able to see whether the new process creates a more dependable response, clearer accountability, fewer avoidable delays, or better quality decisions. That shared understanding makes the automation sustainable and gives the organization a disciplined way to choose the next workflow worth improving.
Business Takeaway
AI scheduling earns trust when it respects real-world constraints and explains its choices. Build it as a dispatch co-pilot: a system that spots risk, proposes a workable plan, and gives people the context to make a better final call.