What Happened
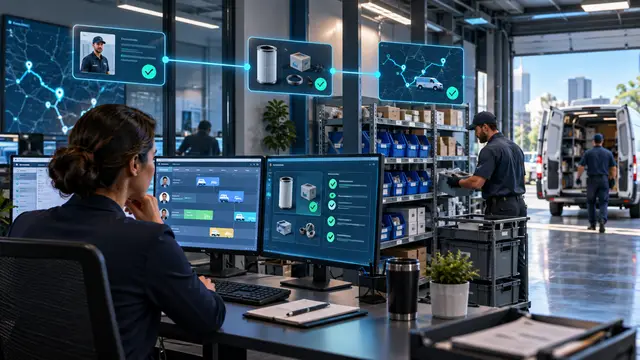
A facilities maintenance work order prioritization process rarely fails because people do not care. It fails because the decision arrives in fragments: a record in one system, a message in another, an attachment that is hard to interpret, and a deadline that appears only after the queue has grown. The people closest to the work compensate with memory, spreadsheets, and quick conversations. That keeps customers moving, but it makes the process difficult to see, improve, or scale.
In many organizations, the same pattern appears every day. A new item arrives and someone must decide whether it is complete, urgent, standard, or risky. The answer depends on details spread across systems and on knowledge that may sit with a few experienced people. The work is often interrupted by requests for status, manual reassignment, and duplicate research. A structured AI and automation workflow can make those dependencies visible without erasing the expertise behind them.
Why It Matters for Businesses
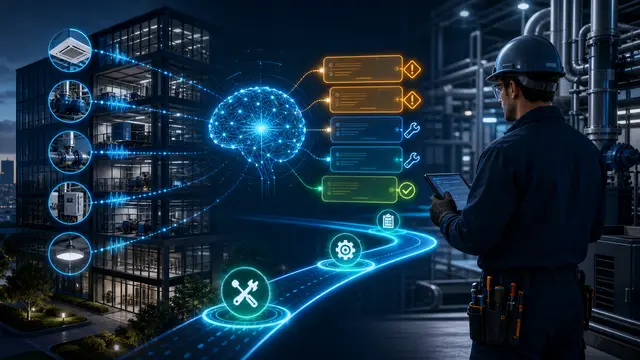
A well-designed workflow protects human attention. It should not use AI to generate more alerts. It should reduce the number of decisions that need a person and improve the evidence available for those that remain. A concise case brief can include the relevant history, a proposed classification, confidence, policy references, open questions, and recommended next action. The reviewer can correct it in seconds, and that correction becomes feedback for the process.
This matters because speed without control is not an improvement. A workflow that rushes weak decisions downstream can increase write-offs, churn, repeat visits, discount leakage, or compliance exposure. The better design balances fast handling for predictable cases with deliberate review for ambiguous ones. It gives the business a common language for why work was prioritized and what happened next.
The Practical Automation Opportunity
Use automation to enforce the operational contract. When a case enters the queue, assign an accountable owner, set a due date based on priority, create only the necessary follow-up tasks, and notify people in the tool where they work. When a decision is made, write the outcome, reason code, and source links back to the system of record. Close the loop with a customer or internal update when appropriate, rather than leaving the status implied.
Useful design principles:
Define a small taxonomy of reasons that people can apply consistently.
Keep a human approval gate for material financial, contractual, or customer-impacting decisions.
Measure queue age, rework, escalation rate, resolution quality, and prevented follow-up work.
Review corrections weekly and convert repeated corrections into clearer rules or better source data.
Publish ownership and escalation rules so automation does not create an unowned queue.
Governance should be present from the first pilot. Limit access by role, minimize copied sensitive data, log prompts and outcomes where policy permits, and define retention for case material. Test the workflow with messy real examples, not only ideal samples. Ask reviewers to look for false certainty, overlooked evidence, biased prioritization, and failure modes caused by incomplete upstream data. A useful control is an exception report that shows what the system could not classify and why.
Roll out in stages. First run the workflow in observation mode, where it produces a recommendation but changes nothing. Compare recommendations with expert decisions and refine the routing thresholds. Next automate administrative actions for high-confidence routine cases. Finally expand to adjacent use cases only after the team can explain the baseline, the safeguards, and the measured benefit. This sequence builds confidence without asking the organization to accept a black box.
A practical scorecard should include leading and lagging measures. Leading measures include percentage of complete intake records, routing confidence, time to first action, and the share of cases resolved on the first pass. Lagging measures include cash collected, retention protected, technician productivity, proposal turnaround, avoided concessions, and customer satisfaction. Select measures that the process owner can influence, then review them with the people doing the work so metric changes are interpreted in context.
Integration details deserve attention. A robust workflow should tolerate delayed syncs, duplicate events, altered records, and failed notifications. Use idempotent actions where possible, validate required fields before downstream changes, and surface an actionable error queue. The process should have a clear manual fallback for outages. Reliability is part of the customer experience, even when the customer never sees the automation directly.
Business Takeaway
The practical opportunity in facilities maintenance work order prioritization is not a generic chatbot. It is an operational design that joins reliable data, transparent AI assistance, accountable people, and dependable follow-through. Choose one recurring source of delay, make the decision path visible, and measure the result from intake through closure. That is how an AI initiative earns trust and produces durable ROI. A clear case record is the foundation. Give every facilities maintenance work order prioritization item a durable identifier, intake timestamp, current owner, reason category, confidence indicator, and next-action deadline. This prevents a common automation mistake: making an impressive recommendation without making work manageable. Employees need to see what changed, what action is expected, and where the supporting evidence lives. Managers need to see whether an item is waiting on data, approval, an external response, or capacity. The workflow should separate recommendation from authority. AI can prepare an explanation of the pattern it detected and suggest a path, while the business defines who may approve an exception or change a record. Thresholds should reflect risk, not technical optimism. A routine item with complete evidence may move automatically; a sensitive, safety-related, contractual, or material item should pause for review. Plan for edge cases that rarely appear in demonstrations. Decide what happens when a source system is unavailable, two events describe the same situation, a key field changes after routing, or the assigned person is absent. Build duplicate checks, timestamped snapshots, retry logic, and a visible recovery queue. Define who owns that queue and the service level for clearing it. Reliable recovery is part of the customer and employee experience. Invite the people who resolve these cases today to shape reason codes, summaries, and review screens. Give them a quick way to mark a recommendation wrong or incomplete. Weekly sample reviews reveal unclear policies, missing data, and handoffs that process diagrams miss. This feedback makes employees partners in improvement and turns corrections into concrete changes in rules, integrations, and training. Report speed alongside quality. A shorter queue is valuable only if the right action was taken and rework does not rise. Compare outcomes by reason, source channel, owner group, and confidence band. Look for recurring causes exposed by the workflow: outdated master data, a confusing policy, a supplier setup issue, an unclear request, or an integration defect. Removing repeat causes often creates more value than automating another click. As the workflow matures, hold a quarterly control review. Confirm that source data still represents the current process, recheck access rights, examine policy changes, test unusual cases, and validate the measures used to justify the system. That governance rhythm keeps AI assistance aligned with operating reality as tools, staff, and priorities evolve. Before expanding, establish a baseline that describes the queue today: volume, age, reason mix, touch count, error rate, and business outcome. Keep that baseline visible through the pilot. It gives the team an honest way to evaluate the workflow and prevents a change in demand from being mistaken for automation value. Use case-level samples alongside dashboards because a metric can look better while important edge cases become harder to resolve. Design the handoff experience with the same care as the AI prompt. The assigned person should receive a concise summary, a link to evidence, an explanation of the recommendation, the due date, and a single clear action. Avoid sending the same alert to several groups. Escalate only after defined conditions, and make the escalation route visible. Clear ownership is often the biggest improvement a workflow creates. Data quality work should be part of the roadmap. Track fields that are frequently empty, sources that disagree, and terms that reviewers interpret differently. Fixing these issues makes both human and automated decisions more reliable. Where a source cannot be trusted, label the limitation rather than allowing the system to imply certainty. Transparent uncertainty protects trust and directs investment toward the highest-value improvements. Make adoption practical. Give users a short guide that explains what the system does, what it does not decide, how to correct it, and where to report a problem. Share early examples in which the workflow prevented delay or exposed a recurring cause. Employees are more likely to use a tool when they can see how it removes low-value searching and gives them stronger context for the decisions that still need their expertise. The resulting capability is a repeatable operating pattern. It can be applied to other workflows only after the first process has clear ownership, dependable data, controlled actions, and credible measures. Scaling responsibly means reusing the pattern, not copying a brittle configuration. Each new workflow deserves its own risk thresholds, evidence rules, and success measures. That discipline is how business automation stays useful as the organization changes.