What Happened
Customer-service teams hold a remarkably detailed record of how a product works in real life. They hear where customers hesitate, which instructions are unclear, which errors repeat, and which feature requests hide beneath a complaint. Yet this evidence is usually trapped in cases, chat transcripts, call summaries, and tags designed for operational reporting. A monthly count of ticket categories may show volume, but it rarely explains what customers were trying to accomplish or why a workaround failed. Product teams therefore receive anecdotal escalation, while support teams keep answering the same questions.
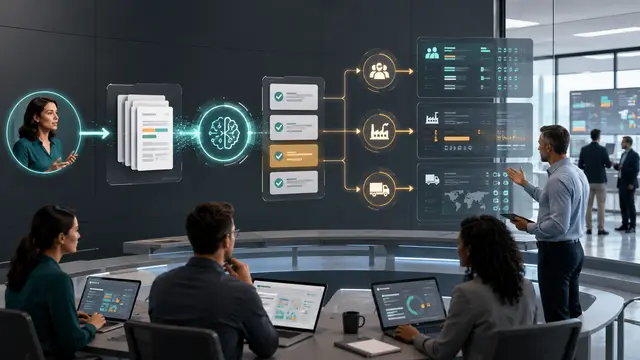
An AI-supported insight workflow can turn conversations into an organized signal without pretending that every request is a roadmap item. It reads completed interactions, removes or masks unnecessary personal data, groups similar issues, and produces evidence-backed summaries. Each summary should preserve the customer outcome being sought, the product area involved, the frequency and business impact, and examples that an employee can inspect. The useful output is not a dramatic prediction. It is a reliable bridge between frontline language and the product, documentation, training, or process team that can act on it.
Why It Matters for Businesses
When service insight is informal, businesses pay twice. Support capacity is spent on repeat contacts, while product and operations teams make decisions with incomplete evidence. Customers may view a confusing setup step as a product defect even when it could be solved by clearer onboarding. Conversely, a small but repeated complaint may reveal a serious accessibility, billing, or reliability issue that deserves rapid attention.
A shared operating view also improves the relationship between departments. Support managers can explain why a pattern matters using examples and measurable impact. Product managers can distinguish between a single loud request and a recurring unmet need. Leadership can see whether a change actually reduced contacts after release. This makes customer service part of the learning system, not simply a cost center that closes tickets.
The Practical Automation Opportunity
Choose one conversation source and a limited set of outcomes first, such as onboarding confusion, billing questions, feature discoverability, or preventable repeat contacts. Define a clear data boundary before connecting transcripts. Personal identifiers, payment details, and sensitive account information should be minimized, access-controlled, and retained according to policy. Then establish a taxonomy that people can understand: customer goal, friction point, product area, likely cause, severity, and recommended owner.
A practical flow can work like this:
- Completed conversations are copied into a protected analysis queue after required redaction.
- AI extracts a concise issue statement and maps it to an existing cluster or marks it as a candidate new pattern.
- The workflow calculates volume, repeat-contact rate, affected customer segment, and operational cost indicators.
- A cross-functional owner reviews the evidence and chooses a response: fix, documentation change, training, investigation, or no action.
- After a change, the dashboard monitors the same cluster to test whether customer effort actually declined.
Guard against false certainty. AI grouping is useful for reducing reading, not for deciding customer importance by itself. Preserve a sample of source conversations, let agents correct categories, and use human review for emerging clusters or high-severity issues. The metrics that matter include time to identify a trend, percentage of insights with an accountable owner, repeat-contact reduction, adoption of knowledge articles, and customer effort for the affected journey.
A successful implementation needs an operating owner, not merely a technical owner. The operating owner defines the outcome, approves the decision rules, reviews exceptions, and makes sure that the people doing the work can influence the design. The technical owner is responsible for reliable integrations, access controls, monitoring, and change management. Both roles need a shared definition of success before the workflow goes live. That definition should name the baseline, the target improvement, the process boundary, and the situations where automation must stop and request help.
Data quality deserves early attention. A workflow can only assemble context that is recorded consistently in its source systems. Before expanding scope, inspect a sample of real records for missing fields, conflicting statuses, stale notes, and unclear ownership. Resolve the few data defects that would change a decision, then document the remaining limitations directly in the work item. This approach is more credible than claiming a perfect data foundation, and it gives users a practical reason to correct information at the point where it is created.
Design the human handoff as carefully as the AI step. Each recommendation should show its source, confidence or limitation where helpful, the next action, and the owner who can approve or change it. A reviewer should never need to hunt across five applications to understand why a case appeared in the queue. If an item is escalated, preserve the history and the decision already made so the next person can continue the work rather than recreate it. Clear handoffs are where automation becomes a dependable operating system instead of another notification stream.
Use a controlled pilot to validate value. Select a representative group, run the new workflow alongside the existing method for a defined period, and compare outcomes rather than impressions. Capture false positives, missed cases, user corrections, unexpected delays, and integration failures. These findings are useful design input, not evidence that the pilot failed. The right question is whether the workflow improves a measurable business result with acceptable effort and risk. Only then should the business standardize the process, train a wider group, and retire duplicate manual tracking.
Monitoring is part of the product. Set a regular review for volume, queue age, exception rate, source-system failures, completion quality, and the business metric the workflow was intended to improve. A sudden drop in volume may signal success, but it may also indicate a broken connector. A sudden rise in exceptions may reveal a policy change, a new customer pattern, or a process defect. Assign someone to interpret these signals and maintain a visible change log whenever rules, prompts, sources, or routing are adjusted.
Finally, make the workflow easy to challenge. Employees closest to customers, transactions, and operations will see edge cases before a dashboard does. Give them a short path to flag a bad recommendation, identify missing context, or propose a rule change. Review these submissions on a predictable cadence and close the loop with the people who raised them. That feedback is what keeps an AI-assisted process aligned with how the business actually works as products, policies, customers, and teams change.
Before launch, test the workflow against a deliberately varied set of historical cases. Include ordinary records, incomplete records, unusual but valid records, and examples that previously caused rework. Ask reviewers to explain whether the recommendation would have helped them make a better decision sooner. Where it would not, distinguish between a missing source, an unclear rule, and a situation that should always remain human-led. This produces a usable exception policy instead of an unrealistic expectation that every case can be automated.
Document the minimum information required for a work item to move forward. A simple checklist may include the originating record, the current status, the reason the item was selected, relevant prior activity, an accountable owner, a next action, and a due date. If a source is unavailable, say so visibly. Hidden gaps create misplaced confidence; an explicit limitation helps the user decide whether to proceed, defer, or escalate.
Leaders should sponsor the change as an improvement to the work, not as a test of employee trust. Explain which repetitive steps will be reduced, which professional judgment remains essential, and how success will be measured. Provide role-based training using realistic examples, then reserve time during the first weeks for questions and corrections. Adoption grows when the workflow respects the expertise people already bring to the process.
Maintain a small governance record for the automation. It should list the business purpose, approved data sources, access roles, retention expectations, decision owners, monitoring metrics, and a contact for incidents or policy questions. Review it whenever a new system connection, audience, or use case is proposed. This discipline makes later expansion faster because the organization can see what was approved, why it was approved, and what safeguards were proven in practice.
Build a review cadence into the calendar from the first day. In the first month, meet weekly to examine real cases and user feedback. After the workflow is stable, review monthly and after any material process, policy, or system change. Keep a before-and-after scorecard that connects process measures to the business outcome. This turns automation from a one-time launch into a managed capability. It also makes the next investment decision easier: the team can show which rule, integration, or training change created value, which assumption proved wrong, and what should be tested next. Continuous measurement protects both customer experience and operational credibility.
Business Takeaway
Customer conversations become valuable when they are transformed into traceable, reviewable evidence. Start with one repeat-contact problem, connect the insight to a named owner, and measure the effect of the resulting change. Over time, this workflow lets the business spend less effort translating complaints and more effort preventing the friction that created them.