What Happened
Data retention is one of those business responsibilities that stays invisible until it becomes urgent. Files accumulate in shared drives, CRM attachments, old exports, email archives, help desk systems, accounting folders, and project workspaces. Some records need to be retained for business, legal, tax, or customer service reasons. Others should be removed because they are outdated, duplicative, sensitive, or no longer useful. Without a repeatable review process, companies carry unnecessary risk and make future searches harder.
AI can help turn retention from an occasional cleanup project into a managed operating workflow. The technology can classify records, detect likely sensitivity, identify duplicates, compare file age with policy rules, and prepare review queues for accountable owners. The system should not blindly delete business records. It should make the review faster, better documented, and easier to repeat on a schedule.
The challenge is that retention work crosses departments. Sales may store old proposals, customer service may store case attachments, finance may store invoices and remittance files, HR may store employee records, and operations may store vendor documents. Each category has different retention needs. A single cleanup rule based only on age can create more problems than it solves. AI is useful because it can help classify context before a human applies policy.
A practical workflow begins with inventory. What repositories exist, who owns them, what types of records they contain, and which records include sensitive information? AI can scan metadata and file content where permitted, group records into categories, and identify areas that require policy mapping. The business can then create review batches instead of asking every department to manually inspect thousands of files.
The value is not just reduced storage. It is reduced confusion and better control. Teams spend less time searching through obsolete material, leaders gain confidence that sensitive information is not being kept casually, and legal or compliance reviews start from cleaner evidence. Retention automation gives businesses a way to manage information with the same discipline they apply to financial or operational workflows.
Why It Matters for Businesses
Old records create practical business risk. A team may rely on outdated pricing, send an obsolete procedure to a customer, keep personal information longer than needed, or produce inconsistent evidence during a dispute. Even when there is no regulatory issue, clutter slows work. Employees search longer, duplicate files multiply, and no one is sure which document is authoritative.
For small and midsize businesses, the problem is often ownership. Everyone agrees that records should be managed, but no one owns the recurring review. IT may own systems, legal may own policy, department leaders may own business context, and employees own the daily habits that create files. AI can help by turning a vague responsibility into concrete queues: review these customer records, archive these completed project files, confirm these sensitive files, and remove these duplicates after approval.
For customer service and sales teams, retention automation protects the quality of answers. If old attachments, outdated proposal language, or expired terms remain easy to find, employees can accidentally reuse them. An AI review can flag stale material and route it to the team that can update or retire it. This improves both speed and trust because teams are searching a cleaner library.
For leaders, the ROI appears in lower manual review effort, reduced storage waste, faster discovery response, fewer duplicate files, cleaner knowledge bases, and lower exposure from unnecessary sensitive records. These outcomes are easier to defend than a generic promise of compliance. They show that information governance can improve daily operations while reducing risk.
The human element still matters. Retention policy depends on business context, customer commitments, contracts, legal holds, and operational needs. AI should prepare evidence and recommendations, but accountable owners should make final decisions for sensitive categories. This balance keeps the workflow practical without turning governance into guesswork.
The Practical Automation Opportunity
A strong first automation is a records classification pass. The workflow can group files by customer, vendor, employee, project, transaction, policy, marketing asset, or operational procedure. It can detect likely personal information, financial data, contract language, or confidential material. The output is a review inventory that shows volume, location, owner, age, and suggested category.
The second automation is duplicate and stale content detection. AI can identify near duplicate versions of the same document and flag records that appear superseded by a newer version. This is especially valuable in shared drives and sales libraries where multiple drafts survive long after a final file exists. The goal is to reduce confusion before someone relies on the wrong version.
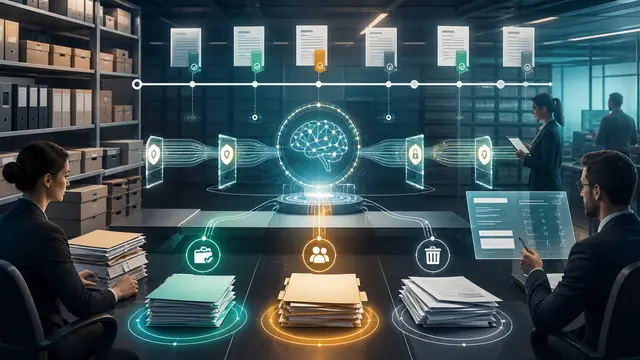
The third automation is policy based review routing. Once categories are defined, the workflow can compare records with retention rules and create queues such as keep, archive, owner review, legal review, customer commitment review, and deletion approval. For records that may be subject to legal hold or contract requirements, the system should require additional confirmation and preserve the decision trail.
Start with one repository and one record category. A good candidate is old customer project files, outdated sales materials, or support attachments beyond a defined age. Document the policy, test the classification, sample the recommendations, and require approvals before deletion. After the workflow proves reliable, expand to additional systems and categories.
Governance should include audit logs, exception handling, and a clear recovery window where possible. The business should know who approved a retention action, which rule was applied, when it happened, and what was excluded. These details matter when someone asks why a record was kept, archived, or removed.
Retention automation should begin with policy translation. Many businesses have a written policy that sounds clear to leadership but is hard for employees to apply. AI can help convert policy into review questions: what type of record is this, who owns it, how old is it, does it contain sensitive information, is it tied to an active customer or contract, and is there a legal hold or business reason to keep it? Those questions make the policy operational.
Another practical design choice is quarantine before removal. For lower risk categories, the workflow can move approved deletion candidates into a restricted review area for a defined period before final removal. This gives owners a chance to catch mistakes and gives the business confidence before expanding the program. For high risk records, deletion should require explicit approval and a documented reason.
The workflow can also improve search quality. When AI identifies current authoritative versions and stale duplicates, teams can prioritize the right files in search results or knowledge libraries. This reduces the everyday cost of messy information. Employees do not need to know the full retention policy to benefit from cleaner folders and clearer source material.
Department owners need simple review experiences. A retention queue should show a small batch, category, suggested action, reason, age, sensitivity indicator, and preview. Owners should be able to approve, reject, reassign, or request legal review. If the review process is too complex, it will stall. AI should reduce the burden, not move the burden into a new interface.
Finally, retention reporting should be executive friendly. Leaders should see records reviewed, records archived, records removed, sensitive items reduced, stale duplicates retired, exceptions pending, and policy areas that need clarification. Those reports show progress and help sustain the habit. Information governance works best when it becomes a recurring business rhythm rather than an annual cleanup scramble.
Access control should be reviewed alongside retention. Old records are more risky when too many people can open them. AI can help identify folders where sensitive or customer specific files are broadly accessible, then route access cleanup separately from retention decisions. This is a practical win because the business may need to keep certain records but does not need to expose them to every employee.
The workflow should also handle business exceptions gracefully. A file may be older than the standard retention window but still needed because of an active customer relationship, warranty obligation, dispute, audit, or long running project. Reviewers need a way to mark the exception, set a new review date, and explain the reason. Without that feature, teams will either delete too aggressively or stop trusting the system.
Training is part of the opportunity. AI can report the habits that create retention problems, such as exports saved in personal folders, duplicate customer attachments, outdated templates, or records stored outside the expected system. Leaders can use those patterns to improve employee guidance and system design. Better habits reduce the amount of cleanup required later.
A final practical step is to publish the review calendar. Departments should know when their records will be reviewed, which systems are in scope, and how exceptions will be handled. Predictability makes retention feel like normal operations instead of a surprise audit.
Business Takeaway
Data retention automation is a practical way to reduce information risk without asking teams to manually clean years of scattered files. AI can classify records, surface sensitive material, find stale content, and route decisions to the right owners.
Begin with inventory and review queues, not automatic deletion. Keep humans accountable for policy decisions and measure the results in faster search, cleaner libraries, lower storage noise, and better control over sensitive information.